Can you trustyour AI judge?
Validate your LLM-as-a-Judge against human review before using its scores to make quality, product, or release decisions.
LLM-as-a-Judge validation · monitoring · revalidation
Overall agreement can hide the failures that matter.
A judge may look reliable in aggregate while underperforming on negative cases, critical failures, or specific evaluation categories.
The question isn't only “what is the agreement?” It's “where can we trust the judge?”
Overall agreement looked strong. Per-class analysis told a more useful story. These numbers are from one live calibration cycle that motivated the methodology. They are not a universal benchmark.
91%
Overall agreement
96%
Critical-class agreement
84%
Negative-class agreement
7%
False-positive rate
An evidence loop, not an accuracy trick.
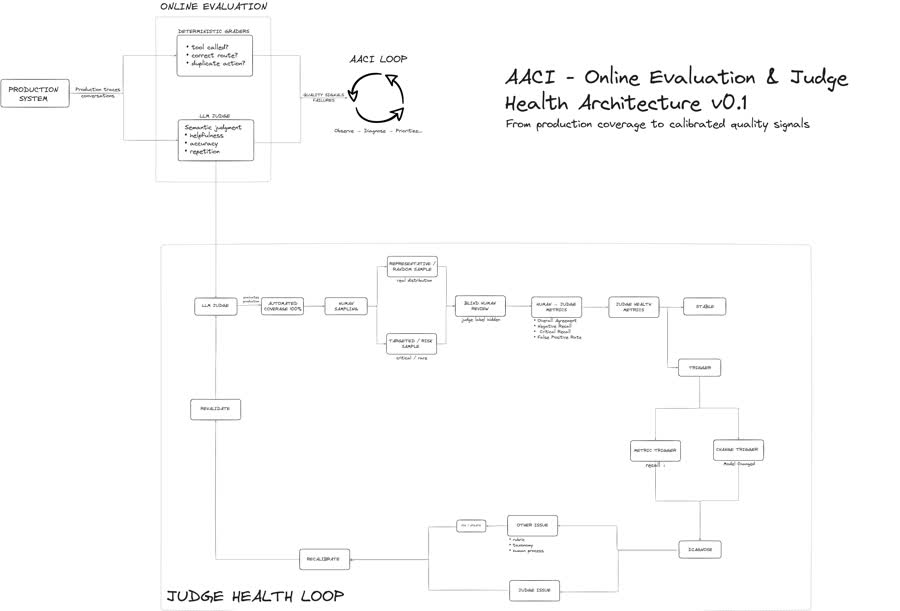
Judge Health compares automated evaluation against human judgment, identifies where agreement breaks down, and defines where the judge has enough evidence to be trusted.
Judge Health Check
A focused validation sprint for teams using or preparing to deploy LLM-as-a-Judge.
What I evaluate
Human ↔ judge agreement · per-class performance · false positives / negatives · critical failure detection · evaluation design
What you receive
Judge Health Report
Clear assessment of where the evaluator can and cannot be trusted.
Metrics & Failure Analysis
Agreement and disagreement patterns beyond the aggregate score.
Evidence Threshold Recommendations
Guidance for what can be automated and where human review should remain.
Monitoring & Revalidation Plan
A practical process for detecting degradation as models, prompts, taxonomies, or production traffic change.
Typical engagement · 3–5 days
Working on the measurement problem beyond a single system.
The work behind Judge Health connects production AI evaluation with a broader question: how do we measure whether AI systems and their evaluators are actually reliable?
NIST · AI Evaluation / TEVV
Public technical comment submitted on AI evaluation and measurement.
NIST · AI Metrology
Measurement methodology submitted to the public NIST AI Metrology Submissions repository.
View public submission →Part of a larger AI improvement problem.
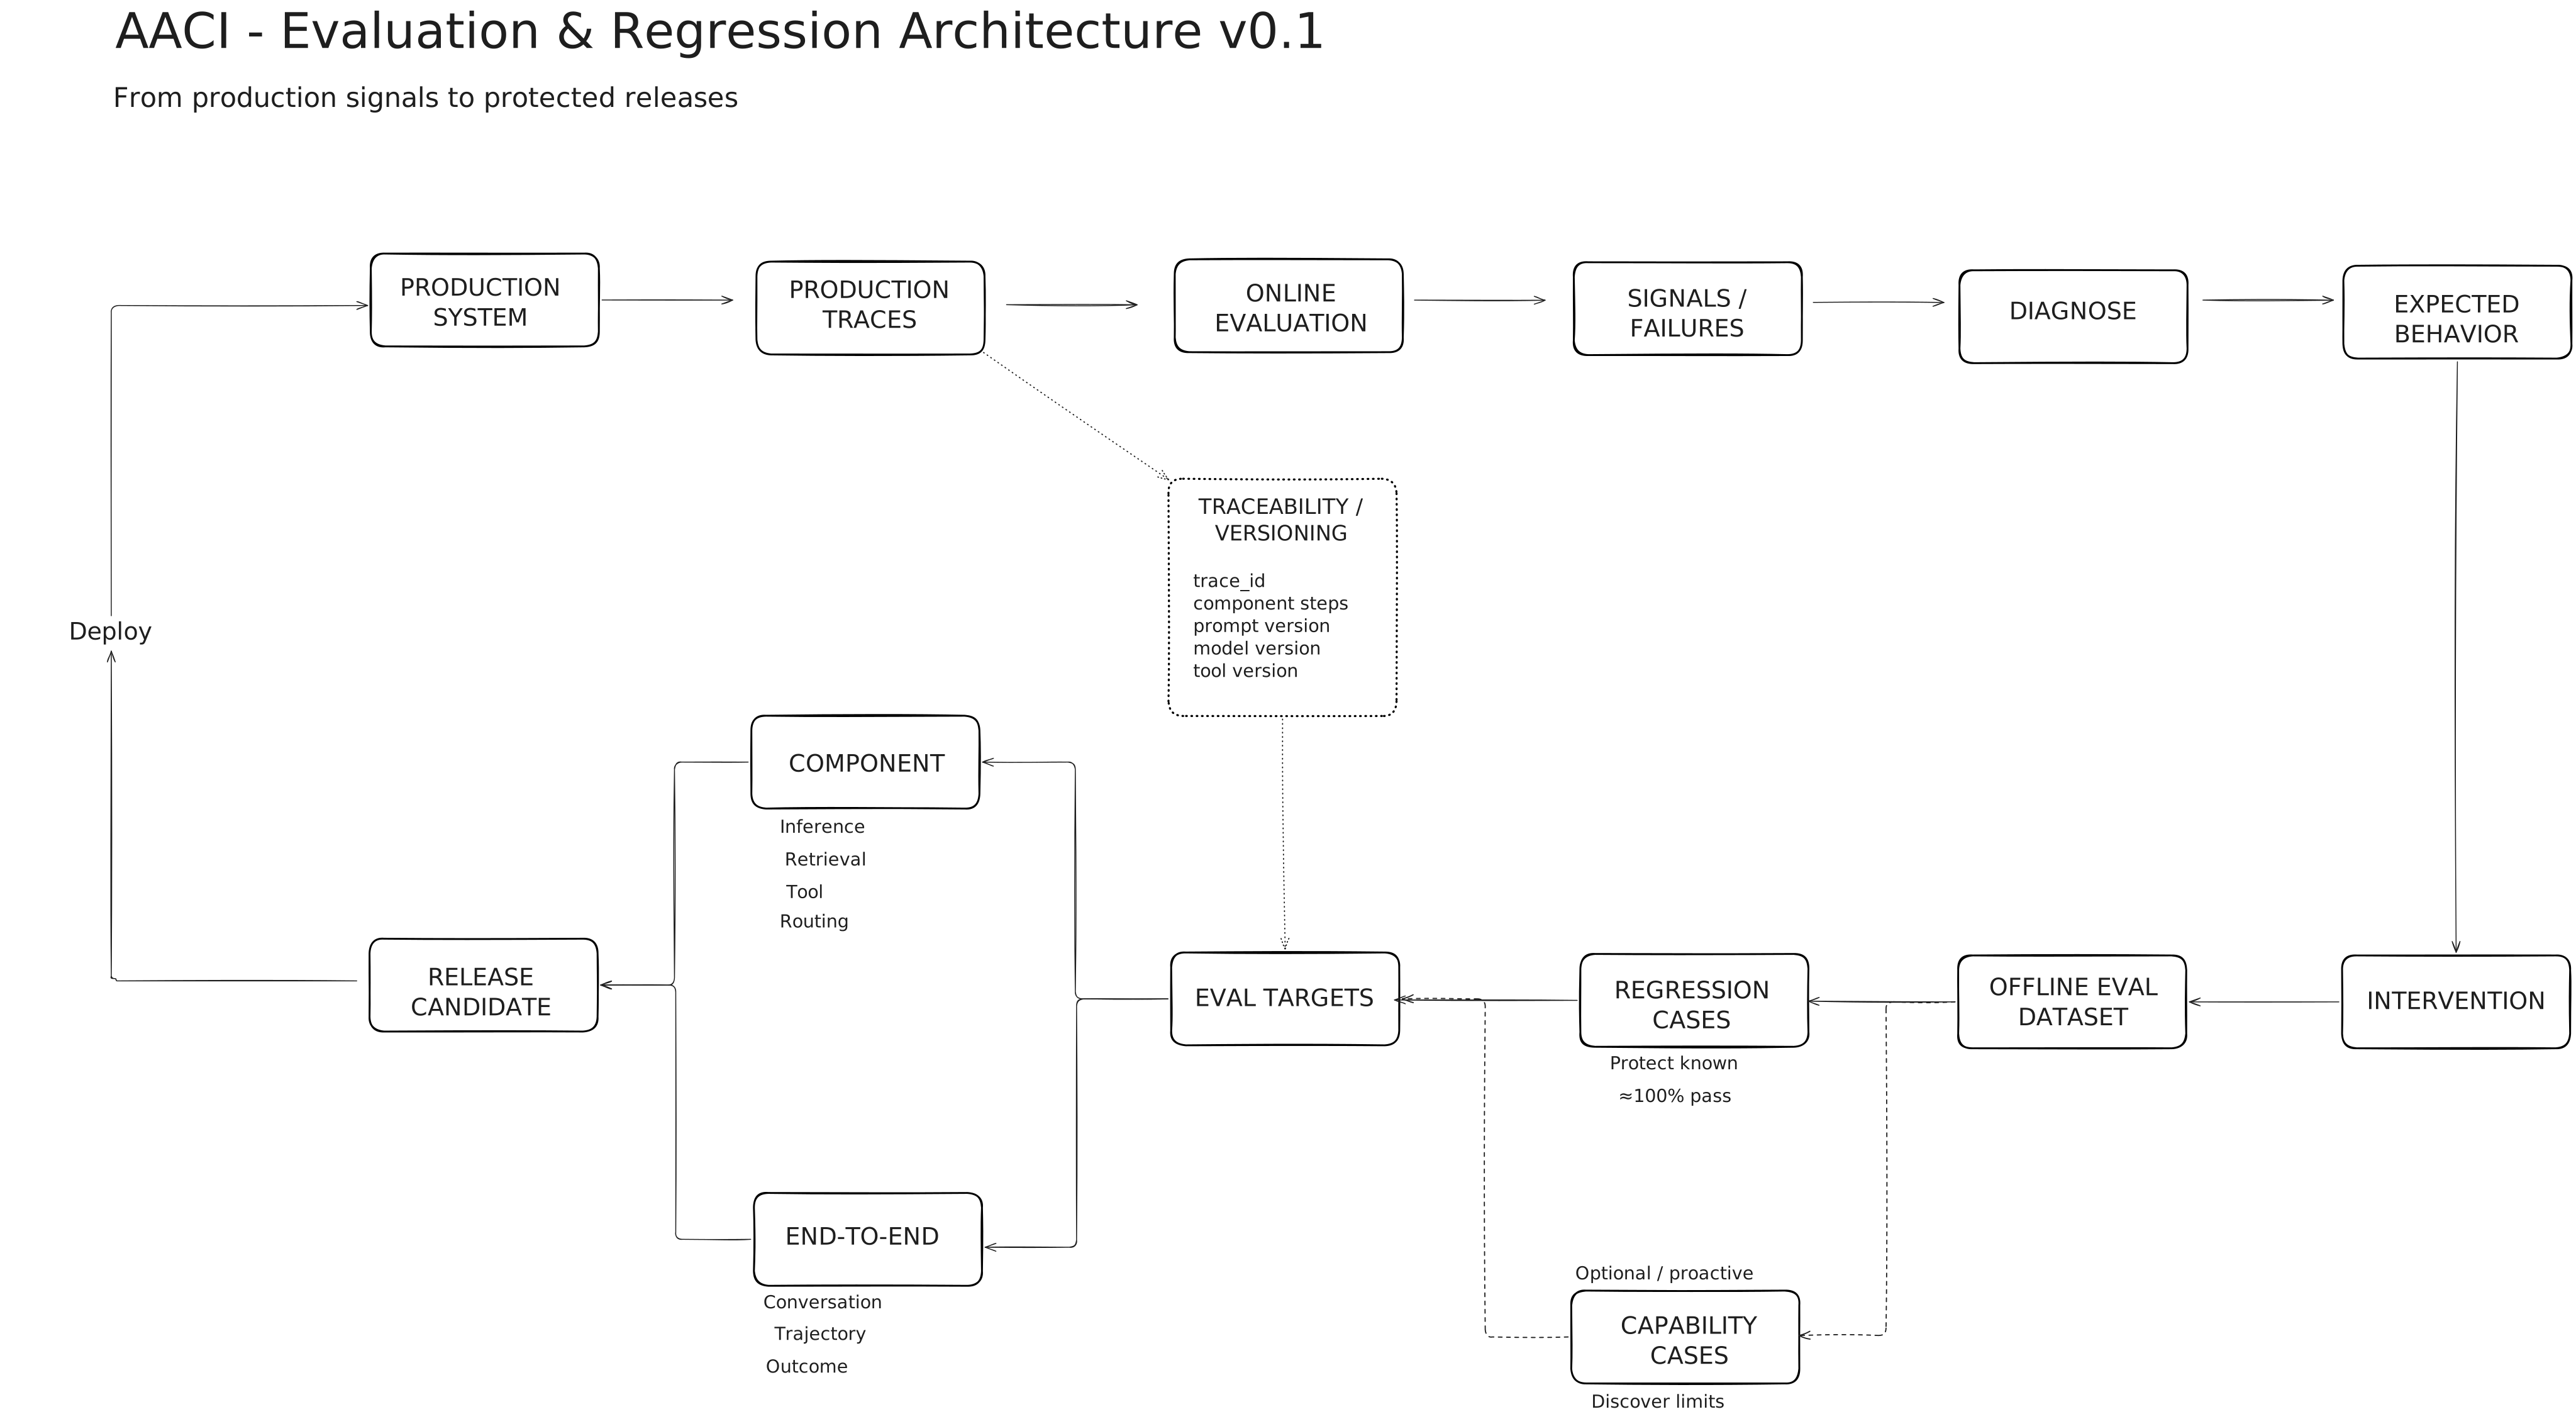
Judge Health focuses on whether automated evaluation can be trusted. AACI looks at the broader system for continuously observing, evaluating, improving, releasing, and monitoring production AI agents.
Your judge produces a metric.
Judge Health tells you whether to trust it.
Validate the evaluator before making quality, product, or release decisions around its scores.